ChatGPT’s crawler spent 34.82% of its fetches on pages that returned a 404. Claude’s spent 34.16%. Googlebot, over the same period, spent 8.22%. Those figures come from Vercel and MERJ’s December 2024 analysis of their network and nextjs.org.
A third of one crawler’s budget hitting dead pages is not a content problem. It is a plumbing problem, and it is the cheapest category of fix in AI search.
The first thing to get right is which bots you want. Two classes do completely different jobs, and most teams block the wrong one by accident.
Which AI crawlers produce citations?
The retrieval and user-triggered fetchers. These fetch your page to answer a question, and they are why your name appears in an answer.
| User agent | Operator | Job | Blocking it means |
|---|---|---|---|
| OAI-SearchBot | OpenAI | Retrieval for ChatGPT search | No ChatGPT citations |
| ChatGPT-User | OpenAI | Fetches a page a user asked about | No live fetch of your page |
| Claude-SearchBot | Anthropic | Retrieval for Claude | No Claude citations |
| Claude-User | Anthropic | User-triggered fetch | No live fetch |
| PerplexityBot | Perplexity | Retrieval and indexing | No Perplexity citations |
| Perplexity-User | Perplexity | User-triggered fetch | No live fetch |
| GPTBot | OpenAI | Training | Your content is not used for training |
| ClaudeBot | Anthropic | Training | Same |
| CCBot | Common Crawl | Open crawl corpus | Same |
| Bytespider | ByteDance | Training | Same |
| Meta-ExternalAgent | Meta | Training | Same |
| Amazonbot | Amazon | Training and Alexa | Same |
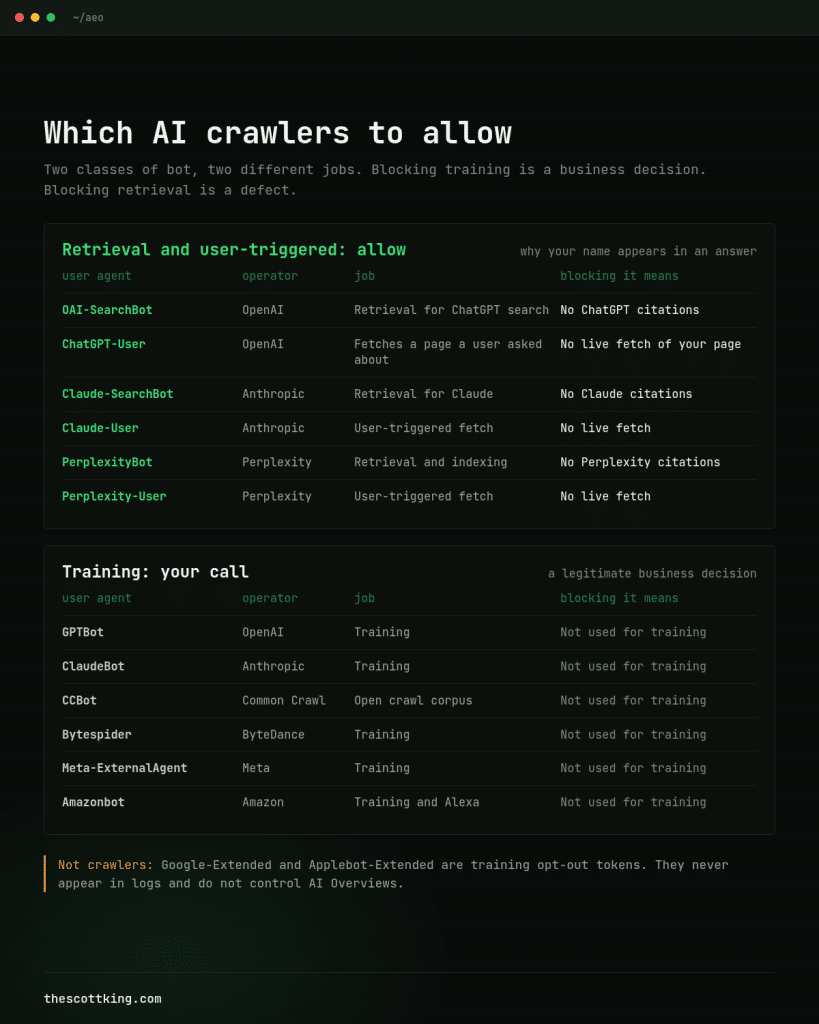
The split is the whole point. Blocking training is a legitimate business decision, and plenty of publishers make it deliberately. Blocking retrieval is a defect, and almost nobody chose it.
Two tokens cause endless confusion. Google-Extended and Applebot-Extended are opt-out signals for training use, not crawlers. Neither will ever appear in your logs, and neither controls whether you appear in AI Overviews.
Why is robots.txt only half the check?
Because your CDN and firewall block at a layer robots.txt never shows you.
Cloudflare began blocking AI crawlers by default on newly onboarded domains on July 1, 2025. Every new zone was asked whether to allow AI crawlers at signup. At the time, the control was effectively all or nothing.
That has changed twice since. On July 1, 2026, Cloudflare split bots into Search, Agent and Training categories. On September 15, 2026, it shipped a Disallow AI Training setting. A site can now stay in search while refusing training use. That matters, because mixed-use crawlers make up 36.6% of verified crawler traffic.
So if your site launched on Cloudflare after July 2025, someone answered that question for you. Go find out which answer they gave.
Call the failure the one-switch block. Someone protecting the site from scrapers flips one toggle. That toggle treats the bot that trains a model and the bot that cites your page as the same thing. The site owner reports that AI crawlers are blocked. Nobody asks which ones.
How do you test what bots actually receive?
Request your own homepage once per user agent. Compare what comes back.
Run six requests, one for each retrieval agent, plus one with an ordinary browser user agent as your control. For each, record five things:
- HTTP status code
- Byte count of the response
- Visible character count after stripping scripts and styles
- Whether your primary claim string appears in the body
- The vary and cache headers
Identical bytes and identical visible text across all six means nobody is discriminating by user agent. A different size, a missing claim, a challenge page, or a bare 429 with no Retry-After is the finding.
Content parity beats a status code on its own. A CDN serving vary: user-agent can hand bots a thinner or stale cached variant while answering 200 to everybody. The status code looks fine. The page the bot reads is not the page you wrote.
Also write down what sits in front of your site. A bare origin server behind a page-cache CDN carries none of the default-block risk. Naming the stack makes the finding checkable by whoever owns it.
What else wastes a crawler’s budget?
Dead URLs that answer 200, mostly.
The soft 404 is the common WordPress pattern. A missing page redirects to a friendly “page not found” screen, which returns a 200 status. To a crawler, every dead link on your site now looks like a valid page. Check the status chain, not the page you land on.
Three more, in order of how often they show up:
- Redirect chains longer than one hop on primary pages.
- Sitemaps listing URLs that no longer resolve.
- Parameter URLs and faceted pages generating thousands of near-duplicate fetches.
This matters more for AI crawlers than for Google. Googlebot absorbs waste at scale. A crawler already spending a third of its fetches on 404s does not.
Does any of this make you citable?
No. It makes you reachable, which is a different thing.
Fixing access is step one of four. The engine has to reach the page. It has to read the claim in the initial HTML. The claim has to be worth selecting. Other sites have to say it too. The order matters, because a perfect robots.txt in front of a claim any competitor could copy buys you nothing.
Most AI crawlers also do not execute JavaScript, so a claim that arrives after hydration is invisible even when access is perfect. The same Vercel analysis found ChatGPT’s crawler fetches JavaScript files on 11.5% of requests and runs none of them.
Once access is clean, go count what the engines actually say. Ten prompts, five runs each, logged out. That number is the one that tells you whether the fix did anything.
Ask your developer this
One question, and it names the owner at the same time. Which user agents can fetch our pages, and did anyone decide that on purpose?
If the answer is a shrug, you have found work worth an afternoon. If the answer is a CDN dashboard nobody has opened since launch, you have found the reason your content is not being cited.
The audit runs the parity matrix across all six retrieval agents. It checks whether your primary claim survives in the initial HTML. It pairs both with 150 observations across ChatGPT, Google AI Mode and Perplexity, so access findings arrive beside the presence counts they explain.

Scott King helps B2B technology companies build AI marketing systems and create differentiated content.